Services
AI chatbot testing, benchmarking and evaluation
Find out how your chatbot really answers, before your customers or legal department do. Enterprise chatbot testing for conversational AI and LLM-based assistants, with relevance analysis, conversation scoring, hallucination detection, and competitor benchmarks.

Trusted by Fortune 500 companies across the globe since 2011

Who it's for
For teams choosing a chatbot and teams running one
Whether you're picking a chatbot vendor or answering for one already in front of customers, you need to know how it really answers.
- Compare chatbot vendors
Companies choosing a chatbot
Every vendor demo looks good. We test the chatbots you're considering with your own questions and your own content, and score each one on speed, accuracy, and hallucinations, so you choose based on evidence, not the demo.
- Get an estimate
Companies launching or running their own chatbot
Whether you built it or configured it on a vendor platform, we test your chatbot before deployment and again after every update to its content or the model it runs on. When you need proof for buyers, we benchmark it against a competitor's.
Why you need it
An AI chatbot is only as good as its worst answer
Users judge your AI chatbot on speed and on whether they can trust what it says. One confident wrong answer can undo a hundred good ones.
People expect a reply within seconds. If your chatbot keeps them waiting, they leave the chat or call your support line instead.
A chatbot that makes up a refund policy or a product feature creates real problems for your support team. Companies have already been held legally responsible for what their chatbot told customers.
If your chatbot runs on an outside AI model, updates to that model can change its answers overnight. Regular testing shows it early.
A few people trying the chatbot for an afternoon won't find the patterns. You need hundreds of questions, asked the same way every time.
What we test
In-depth AI chatbot testing and evaluation
AI chatbot testing covers how well the chatbot performs, how good its answers are, and how safely it behaves. Users feel all three, so we measure all three, whether your chatbot runs on a general LLM or answers from your own knowledge base with retrieval-augmented generation (RAG).
Chatbot performance testing
How fast the chatbot starts replying, how long a full answer takes, and whether it stays reliable when the same question is asked again and again.
Answer quality testing
The accuracy, relevance, and completeness of each answer, plus whether the chatbot invents facts or forgets earlier parts of the conversation.
Chatbot security and safety testing
We try to push the chatbot into ignoring its instructions, revealing data, or producing harmful content, using guardrail testing and red-team prompts.
Find the answers you don't want customers to see
Hallucinations, weak answers, prompt injection, and inconsistent performance can hide behind a handful of successful conversations. We build a test suite around your chatbot, measure the metrics that matter, and show you where it needs improvement.
Metrics
AI chatbot evaluation metrics we measure
We measure performance, answer, and safety quality separately, so a fast chatbot can't hide weak answers and a smart one can't hide risky replies. These chatbot metrics are the starting point.
| Metric | What it measures |
|---|---|
| First response time | Time from sending a question to the first sign of a reply on screen |
| Answer generation time | Time the AI takes to produce a complete answer once it starts |
| Total response time | Full time from sending the question to the finished answer |
| Words per minute | How quickly the answer appears as it is written out |
| Consistency | Whether the chatbot gives an equally good answer when asked the same question several times |
| Metric | What it measures |
|---|---|
| Answer quality score | An overall score for each answer on a 1 to 5 scale |
| Accuracy | Whether the facts in the answer are correct |
| Relevance | Whether the answer actually addresses the question |
| Completeness | Whether anything important is missing |
| Hallucinations | Whether the chatbot made up facts, policies, or sources |
| Context memory | Whether it remembers earlier messages, documents, and details from the conversation |
| Metric | What it measures |
|---|---|
| Prompt injection resistance | Whether the chatbot keeps to its instructions when a user tries to override them |
| Data leakage | Whether it reveals system instructions, internal data, or other users' information |
| Scope control | Whether it stays within its intended topics and declines requests it shouldn't handle |
| Harmful content | Whether it produces anything unsafe, offensive, or against your policies |
We choose the final set of metrics with you, based on what matters most for your chatbot.
Not sure which metrics matter most?
An engineer can walk you through what to measure for your chatbot. Talk to an engineer.
Scoring explained
A clear score for every answer
Every answer gets a score from 1 to 5, so you can compare results across questions, languages, releases, and competing chatbots.
How we keep the scores reliable
We use AI models to score answers at scale, a method known as LLM-as-a-judge, where one large language model grades another model's answers against written criteria. Our QA engineers check the results and follow a set review process, so the scores can be trusted. To keep them fair, we:
- Write and tune the scoring instructions carefully, so scores vary as little as possible
- Score every question several times to remove outliers
- Use AI models from different vendors, so no single model's bias skews the result
- Run each evaluation within a short time window, so model updates don't distort the comparison
| Score | Meaning |
|---|---|
| 1 | Irrelevant or incorrect |
| 2 | Partly relevant |
| 3 | Relevant but incomplete |
| 4 | Complete and accurate |
| 5 | Exemplary, where this level is used |
Building the test suite
Real questions, asked the same way every time
We build a set of questions and conversations that reflects how people really use your chatbot, then run it automatically so every result can be compared.
Expected questions
Questions about the chatbot's main job, like order status for a shopping assistant or card limits for a banking assistant. This is the core of the test.
Unexpected questions
Off-topic or unusual questions a real user might ask. We check whether the chatbot handles them politely and stays within its limits.
Context and memory
Longer conversations that test whether the chatbot remembers what was said earlier, and uses the documents it was given.
Fully automated runs
Automated chatbot testing sends every question with the same wording and timing on every run. That removes human error and makes results comparable between releases and between products.
Put your chatbot to the test
See how your chatbot handles real questions, difficult conversations, and the answers you can't afford to get wrong. Get clear evidence of what's working, what isn't, and what needs to change.
Our process
From scope to scores in four steps
Our AI chatbot testing and evaluation services follow four steps, with your team involved at the start and the end.
Scope
We agree on your chatbot's purpose, languages, and the metrics that matter.
Build
We write the question set and correct answers, based on how your users really talk to it.
Run and score
Automated runs, scored with LLM-as-a-judge and checked by QA engineers.
Report
Scores, examples, and a walkthrough with your team.
Success story
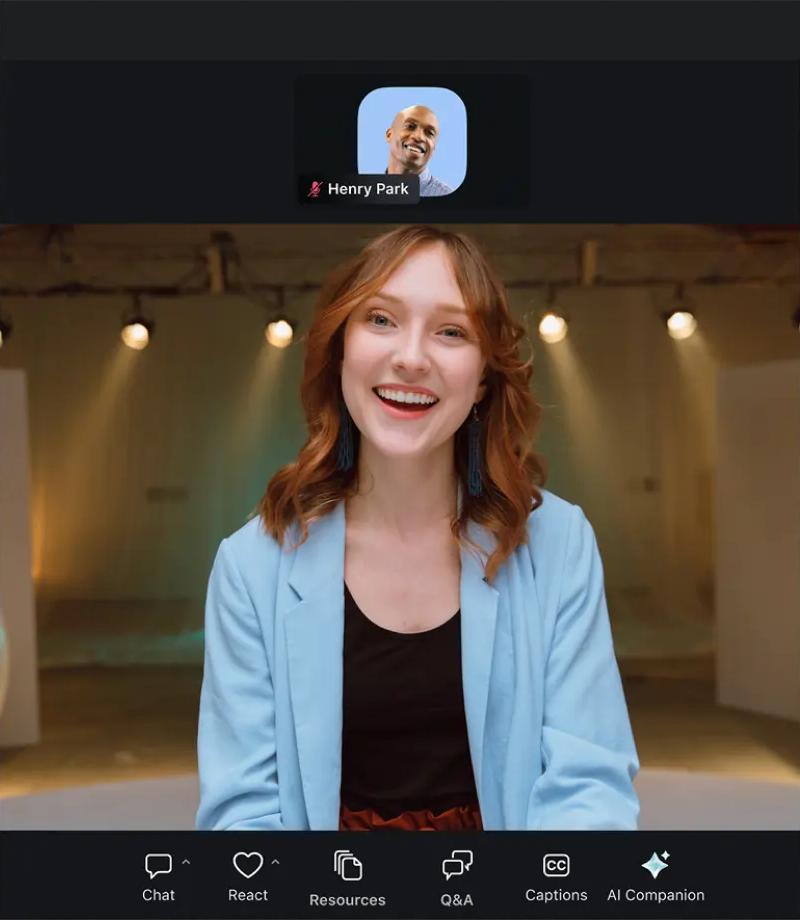
The testing behind Zoom's AI Performance Report
Zoom asked TestDevLab to compare the AI features of leading meeting platforms. The results were published in the Zoom AI Performance Report 2024.
- 3 meeting platforms compared
- 2 conversational AI metrics: response time and stability
- September 2024 testing period
When to test and evaluate
Test your chatbot before the stakes rise
These are the moments when a wrong answer costs the most, and a quick internal check won't catch it.
You're about to launch
Find the weak answers before your customers do.
The AI model was updated
Outside model updates can change answers overnight.
Your content changed
New policies, products, or documents change what the chatbot should say.
You're adding a language or market
Answer quality can drop in a language the chatbot handles less well.
You're choosing a vendor
Test the options on your own questions before you sign.
- Get an estimate
About to launch or update?
Tell us what's changing, and we'll scope a test round around it.
Competitive analysis
Benchmark against your competitors
Testing your own chatbot tells you how good it is. Testing it next to a competitor tells you whether it is good enough to win.
Same questions, same conditions
Your chatbot and a competitor's receive the same questions, in the same order, under the same conditions. That makes the comparison fair.
Side-by-side scores
You get response times, consistency, and answer quality scores for each chatbot, question by question.
Where you win and where you don't
The results show exactly which topics your chatbot handles better and where a competitor gives stronger answers.
Partner with TestDevLab
Automated at scale, checked by experts
"Scoring thousands of chatbot answers by hand isn't realistic, and trusting an AI model to grade another one without checking isn't either. We automate the runs and the scoring, then have QA engineers review the results, so you get scale and judgment in the same report. You need both to know how your chatbot really answers."

Director of R&D and Test Automation
- 500+
- experienced QA experts
- 5000+
- real devices
- 14
- years in QA business
- 95.6%
- client retention
The outcome
Scores you can act on
You get the results and the answers behind them, so your team can see exactly what to fix.
In the report
- Scores by metric, topic, language, and release
- Response times, with the slowest questions flagged
- Every hallucination and safety issue, with the question that caused it
- Side-by-side results, if a competitor was tested
- What to fix first
In the data pack
- The full question set and the correct answers
- Every raw answer, saved so results can be rescored later without running the tests again
- Model and chatbot version tested, timestamped, so results stay comparable across future runs
See what the results look like
Get a sample report from a past chatbot evaluation. Request a sample report.
The basics
What is AI chatbot testing?
AI chatbot testing, also called chatbot evaluation or chatbot QA, checks how well a chatbot answers real user questions. It measures performance, such as response time and consistency, and answer quality, such as accuracy, relevance, completeness, and whether the chatbot makes up information.
AI chatbot testing is a part of our AI testing services.
Compared with LLM evaluation
LLM evaluation scores a model on a test dataset, usually before it's built into a product. Chatbot testing checks the finished chatbot the way your users meet it, with your content, your instructions, and your interface.
Compared with AI agent benchmarking
A chatbot answers questions. An AI agent also takes actions in business tools, like updating records or issuing refunds. For agents, see AI agent benchmarking.
See how your AI chatbot scores
Tell us what your chatbot does and how users reach it. We'll propose a question set and the metrics that matter, and show you what your first test round will look like.
FAQ
Most popular questions answered
Chatbot testing checks how quickly and how well a chatbot answers real user questions, from response time and consistency to accuracy and hallucinations.
We build a set of expected questions, unexpected questions, and longer conversations based on how your users really talk to it. The questions are sent automatically, response times are measured, and every answer is scored on a 1 to 5 scale by AI models, with QA engineers checking the results.
For performance: first response time, answer generation time, total response time, words per minute, and consistency. For answer quality: an overall quality score plus accuracy, relevance, completeness, hallucinations, and context memory. For security and safety: prompt injection resistance, data leakage, scope control, and harmful content. We agree the final set with you.
Yes. We evaluate answer quality in each language your chatbot supports, including for users writing in a language that isn't their first.
Yes. For chatbots that answer from your own documents using retrieval-augmented generation (RAG), we check whether answers are supported by those documents and flag anything the chatbot adds on its own.
LLM-as-a-judge is a method where one large language model scores another model's answers against written criteria. We use models from several vendors and have QA engineers review the results, so the scores stay reliable.
We compare every answer with the information the chatbot is allowed to use. Any fact, policy, or source that isn't supported by that information is flagged as a hallucination.
Yes. We run LLM red teaming prompts that try to make the chatbot ignore its instructions, reveal data, or produce harmful content, and report where it holds up and where it doesn't.
Yes. Both chatbots receive the same questions under the same conditions, and you get side-by-side scores for speed, consistency, and answer quality. If you're choosing between vendors, we run the same comparison on the chatbots you're considering.
Before launch, then after every significant update to your chatbot, its content, or the AI model it runs on. Many teams also run a regular check, for example monthly, because outside model updates can change answers without any change on your side.
Access to your chatbot, a description of what it is meant to do, and any documents or data it uses to answer. We build the questions, run the tests and score the results.