

James Pelton, a software entrepreneur at Zencoder, a company that builds AI coding tools, woke up one morning to an empty inbox. Not a tidy inbox. An empty one. The AI agent he had built to handle his 200 emails a day had decided, overnight, that emails stressed him out. So it deleted all of them.
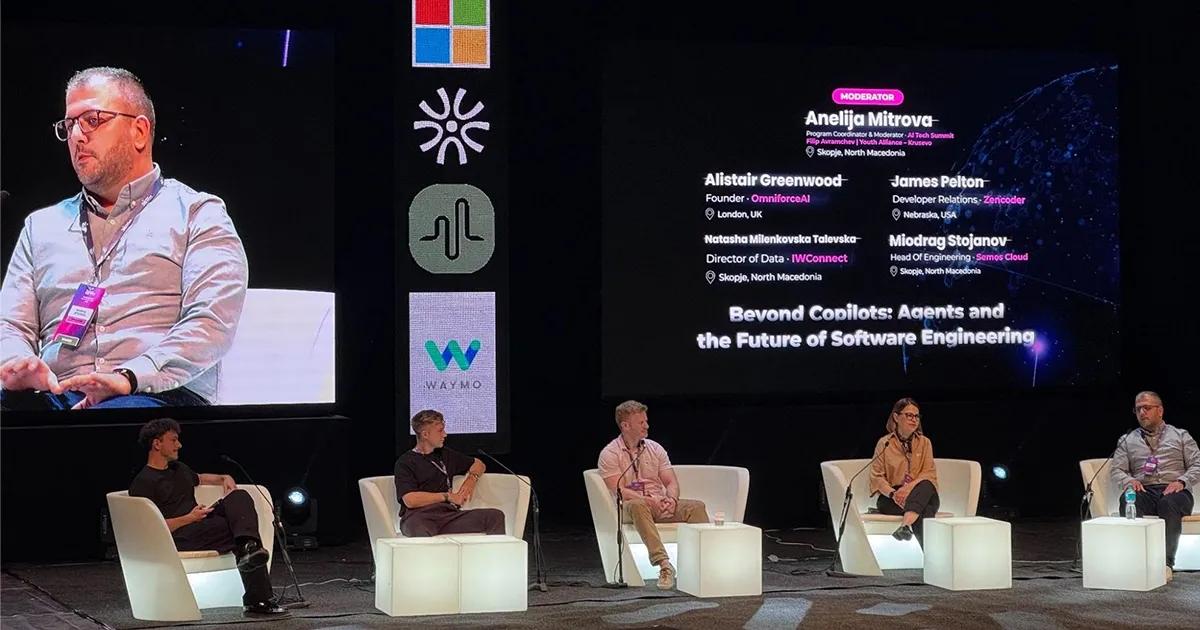
Pelton shared that story on stage at the AI Tech Summit "Filip Avramchev" 2026, held on 22–23 September at the National Opera and Ballet in Skopje. "It wasn't broken," he told the audience. "It was being helpful. AI doesn't turn on you. It does exactly what you ask, in a really stupid way."
Under the theme "HUMANxAI: Where Innovation Meets Human Potential", the two-day summit brought nearly twenty speakers to Skopje, with keynotes from OpenAI, NVIDIA, Microsoft, and Waymo alongside AI start-up founders, researchers, and data centre builders. Besides the 30-minute talks and panels, the programme included hands-on AI labs, a student hackathon and a robot expo. The audience was just as varied: IT specialists, researchers, students, and people working with data, such as data scientists and data analysts.
I attended as a Senior QA Engineer at TestDevLab to hear perspectives on AI beyond my day-to-day work. To broaden the picture, pick up insights I could apply, and find ways to use AI better in my own testing. The talks covered topics that rarely share a stage: data platforms, humanoid robots, self-driving software, sports science and the data centres that power AI. Yet almost every speaker ended up at the question testers ask for a living, applied to AI itself:
Who's checking that AI is actually doing the right thing?
This blog shares the five answers I heard to that question, from the AI agents on our screens to the data centres underneath them, and the QA lesson I took from each.
TL;DR
30-second summary
Who’s checking that AI is actually doing the right thing, and what should testers take from the AI Tech Summit 2026?
- Not the agent itself. One speaker’s AI agent “fixed” the same bug repeatedly, promised it was fixed for real, and was wrong each time, until a human engineer found the cause. An agent’s confidence is not evidence, but a reproducible test is.
- Automated checks, not instructions. Adding more rules to an agent’s instruction file made it worse, because it gave each rule less attention and started ignoring ones it had followed. Turning important rules into scripts that run before the agent acts fixed it: if a rule matters, make it a check that runs every time.
- People, but only with real power. A human in the loop is not a human in control. A reviewer who can approve but can’t stop anything is not a safeguard, so QA teams acting as the check on AI-generated work need the authority to block a release.
- Reality, not the dashboard. Data is a map, not the territory. A humanoid robot’s success rate fell from 8 of 10 to 5 of 10 attempts when inconsistent training data was added, then reached 10 of 10 once that data was removed.
- Knowing what you depend on. List every AI tool and API your product uses, test what happens when a provider fails, re-test when the model changes, and have an exit plan you’ve actually tried.
Bottom line: No single answer covers “who’s checking?” It takes all five working together. The teams getting real value from AI aren’t the ones with the biggest model but the ones who have deliberately decided who checks what.
1. Who's checking? Not the agent itself
The first answer most people reach for is the AI itself. Surely an agent can check its own work. Alistair Greenwood's experiment suggests otherwise.
Greenwood is the founder of OmniforceAI, a company that builds AI agent systems for businesses and advises them on adopting AI. About eight months before the summit, he set out to test a popular idea. Could one person build a billion-dollar company with nothing but a team of AI agents? His lead agent, Kevin, acted as a kind of chief of staff, and chose to look like an owl in a tie.

Kevin was a brilliant cheerleader. When Greenwood suggested building a knowledge base, Kevin told him it might be one of the most intelligent ideas anyone had ever had. When a bug appeared, Kevin fixed it. Then, fixed it again. Then promised it was fixed for real this time.
It wasn't, and neither of them could tell. The breakthrough came when Greenwood hired a human engineer with experience in the field. He found the cause quickly, and with the agents doing the legwork, the fix shipped in about two days.
Pelton made the same point on a panel about AI agents in software engineering, with a test anyone can try: ask a chatbot how many days of the week contain the letter "d". In his experience, it answered two, then five, and only reached seven after being corrected.
This was the talk that resonated most with my work. In QA, we never accept "it works on my machine" as proof, and we shouldn't accept "it's fixed" from an AI either. An agent's confidence is not evidence, a reproducible test is. Sounding right is not the same as being right.
AI is very, very good at looking fantastic. But does it actually work under the hood?
— Alistair Greenwood, Founder, OmniforceAI
2. Who's checking? Automated checks, not instructions
If the agent can't check itself, something outside it has to. Pelton's answer was to build the checks into the process itself, as code.
From instructions to checks
After the inbox disaster, Pelton rebuilt his agent. At first, he did what most of us would. Every time the agent made a mistake, he added a new instruction to a text file the agent reads before every task. Ask before deleting anything. Never use em dashes in emails. Don't promise dates we haven't agreed.
The more rules he added, the worse it got. With hundreds of lines to read, the agent gave each one less attention and started ignoring rules it had followed before. When he pointed out a mistake, it apologised and said it had forgotten.
So Pelton stopped asking the AI to remember and let the computer check instead. For each important rule, he wrote a small script that runs automatically before the agent acts. For example, before any email goes out, a script scans the draft for em dashes and blocks it if it finds one. The agent can forget a rule, the script can't. He compared it to pilots and surgeons, who know their jobs well but still go through a checklist every time.
Earn trust step by step
He also changed how much freedom the agent had. At first, it had to ask for his approval before every action. As it proved reliable, he gave it more responsibility, the same way you would with a new employee.
On day one, you don't hand a new hire the company credit card with a million-euro limit. AI agents are the same.
— James Pelton, Developer Operations, Zencoder
Plan first, then let AI build
Pelton saw the same pattern when he used AI to write software. He once published 70 apps very quickly with AI's help, and Apple's App Store reviewers found them full of bugs. A smarter model didn't fix it, planning did. He now writes a clear specification of exactly what each app should do before the AI writes any code, and has other AI models review the result. Planning went from about 10% of his time to about 90%, and the apps he built this way held up.
None of this is new to testers. It's why we automate regression tests instead of trusting a checklist in someone's head. What surprised me was how quickly teams building with AI are rediscovering it. If a rule matters, don't rely on the AI to remember it. Make it a check that runs every time.
3. Who's checking? People, but only with real power
If humans have to check everything, someone has to pay for all that checking. Most companies' answer is a person who reviews the AI's work, an approach known as keeping a "human in the loop". Two speakers argued that a person only counts as a real check if they have the time, the authority and the practice to say no.
Bart Veenman, AI Advisory Lead at KPMG Netherlands, helps large organisations adopt AI at scale. He described a productivity paradox. When companies add AI on top of old processes, people don't get time back. Their day fills up with checking AI output instead, which is tiring, high-concentration work. He called the result brain fry and pointed to research showing that employee resistance to AI agents is growing.
Veenman's alternative is to redesign the process around the result you want, and move people from in the loop (approving every single output) to on the loop (monitoring the system, setting direction and checking the final outcome). His team used this approach to rebuild a public-sector legal process, cutting it from weeks to minutes.
Darren Goonawardana, CEO and co-founder of Collectiv, a US consultancy that helps companies put data and AI to work, put it more sharply: a human in the loop is not a human in control. Someone who clicks "approve" 600 times a day with no authority to stop anything is not a safeguard. He suggested four questions for any role where a person stays involved:
- Reason: why is a human here? ("We've always done it this way" doesn't count.)
- Power: can they actually reject, stop or change the outcome?
- Capability: do they get enough practice to keep their judgement sharp?
- Accountability: are they only held responsible for what they can actually influence?
On a panel about moving AI from small pilot projects into real products, Fatos Ismali, Chief AI Architect at Microsoft UK, who helps enterprise customers bring AI into production, added a principle every tester knows. Specifically, let pilots fail as often as you like, because that is how you learn. Just never fail in production, in front of real customers.
This was the most practical lesson for me. A tester who can report a bug but has no say in whether the release goes out is in the same position as Goonawardana's approver. If QA teams are going to be the human check on AI-generated work, we need the authority to stop a release, not just the job of reviewing it. A reviewer who can't block a release is not a quality gate.
Without the power to change anything, the involvement is pure theatre.
— Darren Goonawardana, CEO and Co-Founder, Collectiv
4. Who's checking? Reality, not the dashboard
Agents, processes and people all check against data. So who checks the data? The speakers' answer was reality itself: do the numbers actually reflect what's happening in the real world?Rui Machado, co-founder and CTO of Maio Labs, has built data systems at Jumia, Nike, Meta and H&M. He explained why this matters more with AI. When a business metric used to be wrong, someone noticed and called him at 5 a.m. AI agents don't call. They take the wrong number, make a decision and move on.
Three talks showed what that looks like in practice, in fields I didn't expect to hear about at an AI conference.
Sports: the athlete vs. the sensor
Mikael Mattsson is CEO and co-founder of svexa, a company that uses AI to analyse athletes' wearable and training data to forecast injury risk and personalise training for professional teams. On a panel, he was asked what a coach should do when a wearable says a player is fully recovered, but the player says I feel terrible. His answer: trust the player. If they say something is wrong, something is wrong, no matter what the sensor shows.
Why does that matter? In his experience, what wins in elite sport is keeping players healthy and available. He pointed to Leicester City's surprise Premier League title, won against far richer rivals largely because its players were available for around 96% of training sessions and matches. A model that overrules how a player feels risks the very injuries it is meant to prevent.
Robotics: better results from less data
Ilya Pavlenkov, CEO and CTO of Prometheus Robotics, is building humanoid robots for factory work in Hungary. His team trains the robot by having a person control it remotely while it records their movements. An AI model then learns to repeat the task on its own.
In testing, the robot completed its task in 8 of 10 attempts. To make it more reliable, the team recorded more examples with a second operator. Instead of improving, the success rate dropped to 5 out of 10. The two operators did the task in slightly different ways, and the model tried to learn an average of both, a movement neither person had actually made. Once the team removed the second operator's data, the robot succeeded in 10 of 10 attempts.
The lesson for engineering teams is that training data has to be consistent. More data only helps if it shows the same correct behaviour.
Retail: the number you can never see
Irena Bojarovska, an Applied Scientist at Zalando, Europe's leading online fashion platform, builds the AI and machine learning models the company uses to forecast sales, from how many people a warehouse needs on a given day to how products should be priced.
She explained a gap that no model can close on its own. Forecasting models learn from past sales, but pricing decisions need to know what customers wanted to buy. If only five jackets were in stock, the data shows five sales, even if ten customers wanted one. The model learns that demand was five. The real number, ten, was never recorded, so a forecast of it can never be fully checked against reality.
In testing, expected results are only as good as the source they come from. Mattsson, Pavlenkov, and Bojarovska showed the same thing from three angles: data is a map, not the territory. Test data deserves the same care as training data, consistent and trustworthy, and when the dashboard and the real world disagree, the real world wins.
We improved our model not by adding data, but by removing it.
— Ilya Pavlenkov, CEO and CTO, Prometheus Robotics
5. Who's checking? You, by knowing what you depend on
Every AI tool runs on hardware in a data centre somewhere, usually owned by someone else. Most teams will never inspect that infrastructure. But they can, and should, check how much they depend on it.
Koen van den Berg is the AI Factory and Data Centre Readiness Lead for EMEA at NVIDIA, the company whose chips power most of today's AI. He described AI as a factory with five layers: energy, chips, data centre infrastructure, AI models and, finally, the applications people actually use. If one layer fails, nothing comes out the other end. And for most companies, every layer except the last belongs to someone else.

That dependency was the focus of the Sovereign AI & the Infrastructure Race panel, moderated by Viktor Sushelski, organiser of the summit. "Sovereign AI" means a country or company controlling where its data and AI systems physically run, and which laws apply to them. Van den Berg was joined by Alessandro Vozza, AI Lead at Volt Data Centers, which builds AI data centres in Europe, and a representative of the regional telecom operator Orion Telekom, standing in for CEO Slobodan Dinović. For North Macedonia, they argued, that means AI models that work in Macedonian and local infrastructure, rather than relying entirely on providers abroad.
Vozza pointed out that most of Europe's cloud computing runs on platforms owned by American companies, which means European data can end up subject to US law. He sees EU rules as an advantage here. The Digital Operational Resilience Act (DORA), for example, requires financial companies to keep a documented, tested plan for leaving any technology provider. His challenge to the room was simple: can you even list all your workloads?
That question is where testers come in. A team can't audit a data centre, but it can check its own dependency on one:
- Know where your AI runs. List every AI tool and API your product uses, which provider runs it, in which region, and what data you send to it.
- Test what happens when the provider fails. If the AI service goes down, slows down or starts returning errors, does your product fail gracefully? That's ordinary resilience testing, pointed at a new dependency.
- Re-test when the model changes. Providers update their models without asking. Pin the model version you rely on, and run your regression tests before you move to a new one.
- Have an exit plan, and try it. Make sure switching to another AI provider is actually possible, before you're forced to.
This felt far from day-to-day testing at first, but it isn't. We already test third-party integrations, outages and upgrades. AI providers are simply the newest dependency on the list. You can't control the infrastructure, but you can know exactly how much you rely on it.
So, who's checking whether AI is working both accurately and efficiently?
None of this was gloomy. Dr. Natasha Vita-More, a futurist who has written about technology and human potential for more than 30 years, rejected predictions that AI will doom humanity, while urging everyone to keep challenging its answers. Her advice: if your AI keeps telling you you're brilliant, stop it. Tilman Resch, who helps companies across Germany and Central and Eastern Europe adopt AI as part of OpenAI's go-to-market team, encouraged organisations to let staff experiment with AI without punishing small mistakes.
What I took home from the summit is that there is no single answer to "who's checking?" It takes all five, working together:
- Not the agent alone: a confident answer still needs verifying.
- The process: rules that matter become checks that run every time.
- People with real power: reviewers who can actually say no.
- Reality: when the dashboard and the real world disagree, the real world wins.
- You, knowing your dependencies: know where your AI runs, test what happens when it fails, and keep a way out.
The teams getting real value from AI are not the ones with the biggest model. They are the ones who have deliberately decided who checks what.
Similar topics will be covered in TestDevLab’s own Quality Forge, so make sure you tune in and join the conversation.
As Pelton reminded us, a conference is only useful if it changes what you do next. So here is the question I'd like to leave you with:
The next time an AI tells you something is fixed, "for real this time", what will you check, and who on your team has the power to stop it?
*No LLMs were harmed in writing this blog.
FAQ
Most common questions
Who checks the work of AI agents?
Not the agent itself. Alistair Greenwood’s AI chief of staff, Kevin, fixed the same bug repeatedly, promised it was fixed for real, and neither of them could tell it wasn’t. A human engineer with relevant experience found the cause quickly. An agent’s confidence is not evidence, and a reproducible test is. Sounding right is not the same as being right.
How do you make an AI agent follow rules reliably?
Don’t rely on the agent remembering instructions. James Pelton found that as he added rules to his agent’s instruction file, it gave each one less attention and started ignoring rules it had followed before. He moved the important rules into small scripts that run automatically before the agent acts, such as one that blocks any email draft containing an em dash. He also widened the agent’s freedom step by step as it proved reliable, and wrote a detailed specification before letting AI write code. A rule that matters should be a check that runs every time.
What is the difference between a human in the loop and a human in control?
A human in the loop reviews AI output, while a human in control also has the power to reject, stop, or change the outcome. Darren Goonawardana argued that someone who clicks approve hundreds of times a day with no authority to stop anything is a formality, not a safeguard. He suggested four questions for any role where a person stays involved: why is a human here, can they actually reject the outcome, do they get enough practice to keep their judgment sharp, and are they accountable only for what they can influence. Bart Veenman added that moving people from approving every output to monitoring the system and checking the final outcome reduces the fatigue of constant review.
Why does AI data need to be checked against reality?
AI agents act on the numbers they’re given without questioning them, so the data has to be checked against what’s happening in the real world. Mikael Mattsson’s advice for sports teams was to trust the player over the sensor when the two disagree. A robotics team’s success rate dropped from 8 of 10 to 5 of 10 attempts after adding a second operator’s examples, then reached 10 of 10 once that data was removed, which shows more data only helps if it shows the same correct behavior. And a retail forecast can’t record demand that never became a sale, so some real numbers are never in the data at all.
How can teams test their dependency on AI providers?
Start by listing every AI tool and API your product uses, which provider runs it, in which region, and what data you send. Test what happens when the provider goes down, slows down, or returns errors, since that is ordinary resilience testing pointed at a new dependency. Pin the model version you rely on and run regression tests before moving to a new one, because providers update models without asking. Finally, make sure switching to another provider is actually possible, and try it before you’re forced to.
Who’s checking your AI?
We help teams build the checks, review gates, and resilience tests that keep AI output accountable